GPT OSS 20B on Jetson

One-click SSH deployment of GPT OSS 20B on NVIDIA Jetson with a prebuilt Docker image.

SenseCraftBeginner10minOn-Device LM

Reusable Site Templates

Sites that need a large-language-model backend with no cloud connection, where conversations must not leave the local network.

  • Backend for a local chat app — the app calls the device in OpenAI format, with no cloud API key.
  • Offline voice assistant — speech recognition in front hands text to the local model for the reply.
  • Multi-platform chat gateway — with the OpenClaw gateway, WeChat, Telegram and other platforms share this one local model.

Not a fit: long-context or many-user concurrent workloads. The default context is 1024 tokens; keep single requests under 1000 tokens.
How it works

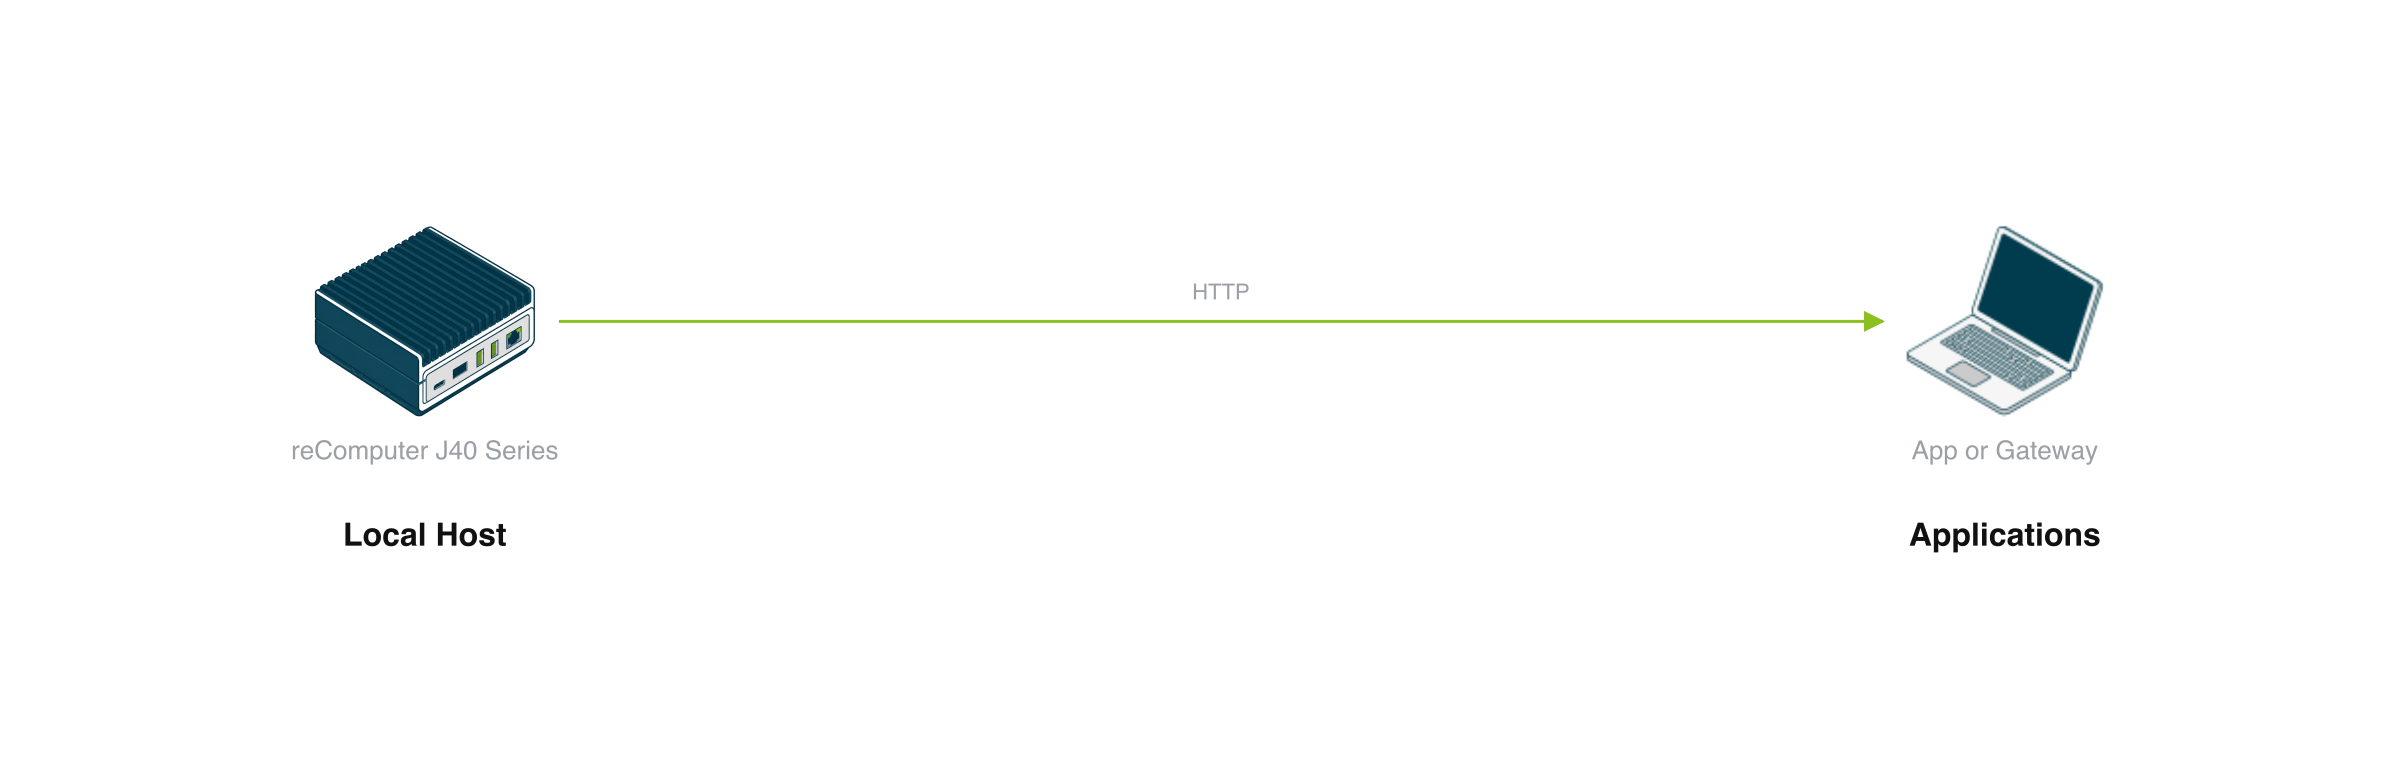
GPT OSS 20B device composition: a reComputer J40 Series host serves chat to an app or gateway over HTTP

One Jetson host is all it takes. The model and inference server sit in one Docker container and open an OpenAI-compatible API on the LAN for your app or gateway to call.

Local Host

The 20B model needs about 12-15GB of GPU memory, which is why the host must carry the 16GB module.

ItemDetail
HostreComputer J40 Series (J4012, Orin NX 16GB)
PrerequisitesDocker and the NVIDIA container runtime installed, SSH reachable
GPU memoryAbout 12-15GB; container memory capped at 12GB

The container runs the llama.cpp inference server with GPT OSS 20B quantized to 4 bits.

  • 20 GPU layers by default: lower it, for example to 16, if memory runs out.
  • 1024-token context by default: a larger context uses more memory; drop to 512 if startup runs out.
  • The first request warms up: the first call after deployment can wait 2-5 minutes.

How well it works

The table lists what this design provides on the reComputer J40 Series (J4012, Orin NX 16GB), and its limits.

What it doesLimit
A 20-billion-parameter model answers on the device, with no cloudDefault context is 1024 tokens; keep requests under 1000 tokens
OpenAI-compatible API for existing SDKs and gatewaysThe first request after deployment warms up for 2-5 minutes
The container starts with the deviceNeeds the Orin NX 16GB module; the 8GB module does not fit it

GPU layers and context length are deploy-time settings; raising them costs more GPU memory.

What you get out of it

Once deployed, this is the interface.

InterfaceWhat comes outNotes
HTTP 8080 chat completionsOpenAI-format requests and repliesAn existing OpenAI SDK only needs a new base URL
HTTP 8080 model listWhether the model is readyReturns 503 while warming up
HTTP 8080 web pageA browser chat pageFor quick trials

The API is served on the LAN with no built-in authentication; put a reverse proxy with access control in front before exposing it to other networks.

How to deploy

Check the setup and its product list, then follow the deployment guide.

Deployment Options

Jetson GPT OSS 20B Service

Deploy GPT OSS 20B inference service to Jetson with one click.

2 steps · ~10min

Edge Device
recomputer_j40

FAQ

A reComputer J40 Series model with the Orin NX 16GB module, such as J4012. The 20B model needs about 12-15GB of GPU memory, which the 8GB module cannot hold. Local deployment also needs 20GB or more of free disk.

Didn't find your answer?
Contact Us
We Are Glad to Be Your Hardware Partner !
Next