Local Voice Service

A local speech service for your own application — send audio in and get text back, send text in and get speech back. Runs on reComputer J40 / J30, reComputer RK3588 / RK3576 or Pi 5, offline after the first deployment.

Beginner15minAcoustic & Audio AISource Code

Reusable Site Templates

Products that need to listen and speak, and cannot send audio to a cloud speech API.

  • Voice-controlled robots — spoken commands become text for your control logic; the reply is spoken back.
  • Kiosks and service terminals — visitors ask out loud and hear the answer.
  • Industrial voice commands — operators trigger actions without touching a screen.
  • One shared voice host — several devices on the LAN send audio to one edge box.

Not a fit: a finished voice assistant out of the box. This service does listening and speaking only; the conversation logic or model is yours to connect.
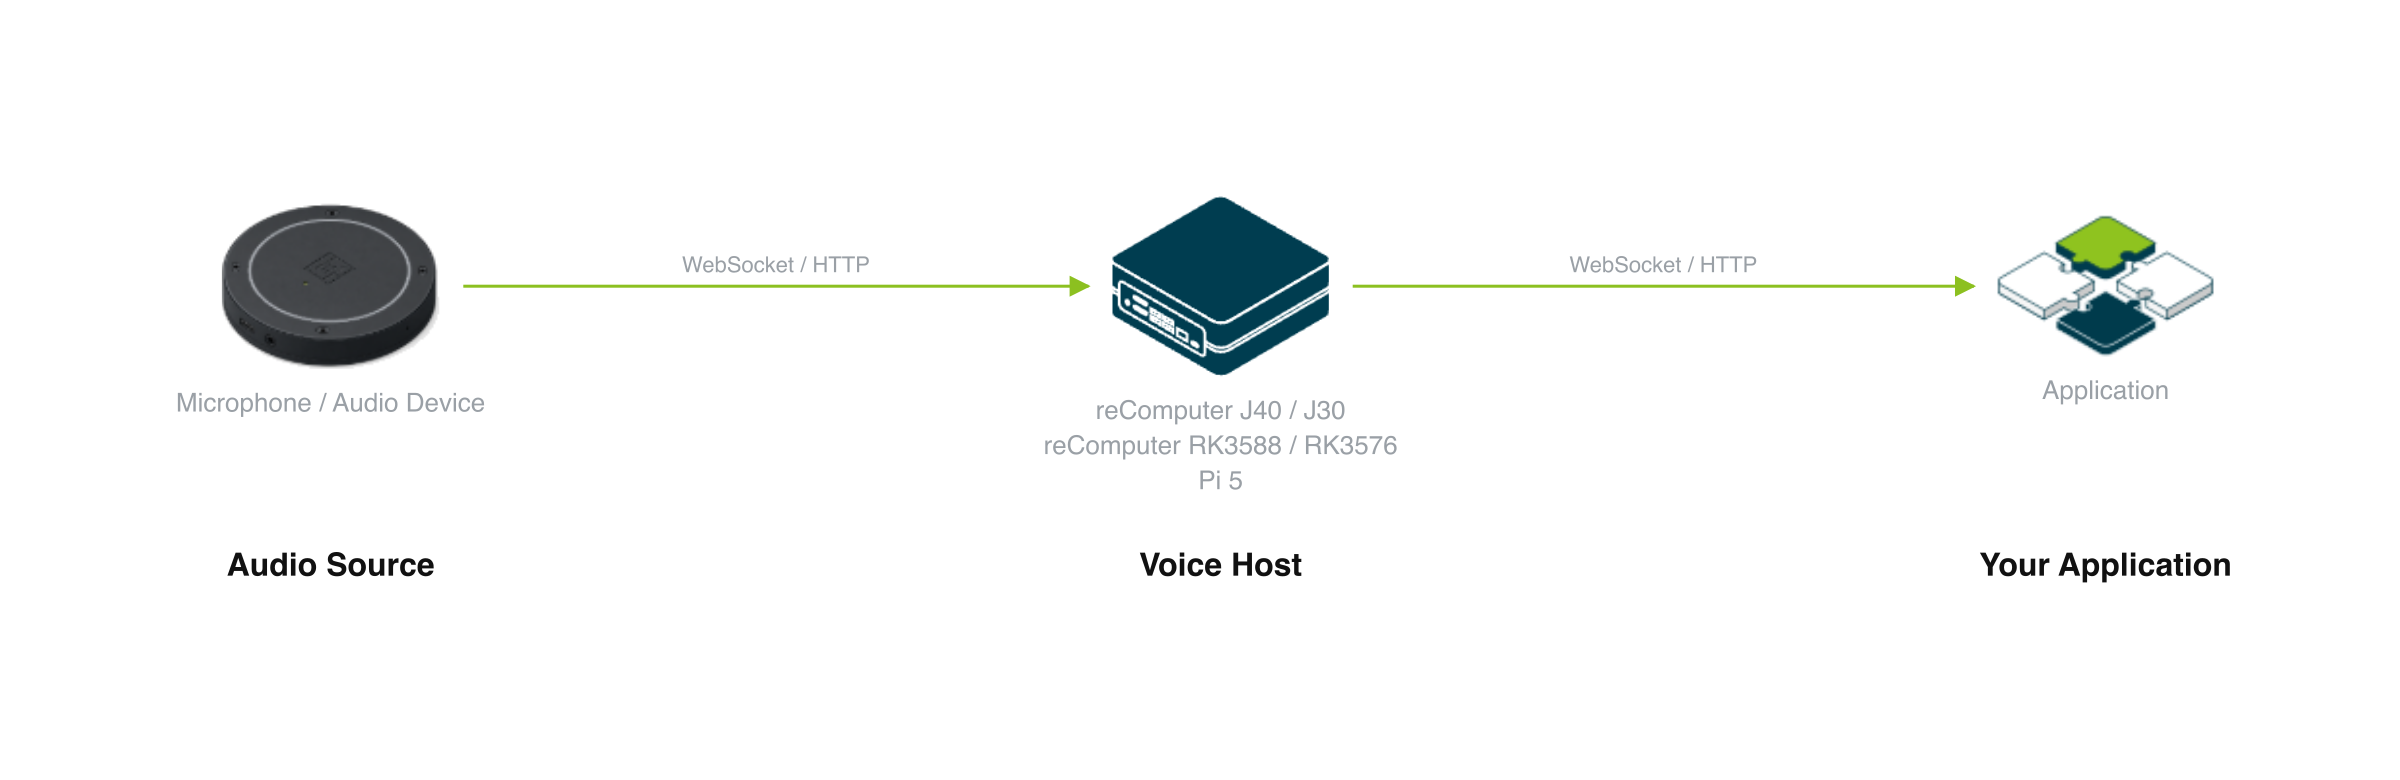
How it works

Local voice service device composition: audio from a microphone or another device reaches the voice host (reComputer J40 / J30, reComputer RK3588 / RK3576 or Pi 5) over WebSocket / HTTP, and your application gets text and speech back over WebSocket / HTTP

Three things: a source of audio, one edge host that runs recognition and synthesis, and your application that calls it over the LAN. Audio and text stay on that host. The internet is needed only for the first deployment, to download the image and models.

Audio Source

The service takes audio from your program, not from a microphone it owns.

  • A microphone on the host — your program captures it and streams it in.
  • Audio from another device — a robot, kiosk or web page sends it over the LAN.
  • Recorded files — upload a WAV and get the transcript back.

Playback is also your program's job: the service returns an audio stream or a WAV file. If users must be able to interrupt the reply, use a microphone with hardware echo cancellation; the Conversational Voice AI reference design covers that setup.

How well it works

Measured with a client-marked end of speech to the first frame of synthesized audio. No conversation model and no silence-detection wait are in the loop.

What the user getsTypicalDevice
Speech recognition to first synthesized audio (Chinese + English profile, excludes VAD and LLM)58 ms p50reComputer J40 series (Orin NX 16GB)
Recognition error, same profile10.5% CER p50reComputer J40 series (Orin NX 16GB)
Speech recognition to first synthesized audio (Qwen3 multilingual, excludes VAD and LLM)162 ms p50reComputer J40 series (Orin NX 16GB)

The same measurement gives 528 ms on reComputer RK3588 and 1020 ms on reComputer RK3576. On J40, Qwen3 recognition lowers the error to 5.3% CER.

In a live product, add the silence your turn detection waits for and the response time of your conversation model. Two sessions at once run on J30, J40, RK3588 and RK3576; on Jetson, synthesis falls behind real time with two sessions.

What you get out of it

All interfaces are served by the voice host on port 8621.

InterfaceWhat goes inWhat comes out
ws://<host>:8621/asr/streamAudio as 16-bit PCMRecognized text as it arrives, with a final flag
POST http://<host>:8621/asrA WAV fileRecognized text
POST http://<host>:8621/tts/streamText as JSONPlayable raw PCM stream
POST http://<host>:8621/ttsText as JSONOne WAV file
GET http://<host>:8621/health—Whether recognition and synthesis are ready

The integration point is your application. Put your conversation model, rules engine or robot command layer between the recognition result and the synthesis request.

Porting It to Your Own System

The reusable unit is local recognition plus local synthesis behind stable HTTP and WebSocket interfaces. What sits between them is up to you.

LayerWhat porting costs you
Recognition and synthesis on four accelerator typesreuse as-is
Interfaces on port 8621reuse as-is
Voice profile, speaker and speedpick in device settings
Conversation model, rules or robot commandsthis is where your product goes
Microphone capture, playback, barge-inbuild in your application, or start from Conversational Voice AI

Where this shape does not fit

  • A product that needs interruption out of the box — use Conversational Voice AI, which adds echo-cancelled capture and barge-in.
  • Languages outside the 52-language Qwen3 list, or anything beyond Chinese and English on Pi 5.

How to deploy

Check the setup and its product list, then follow the deployment guide.

Choosing a host

  • Lowest latency, or voice clone → reComputer J40 series. 58 ms end of speech to first audio. Cost: the highest board tier here, and 7.5 GB of disk.
  • Jetson on a smaller budget → reComputer J30 series. Same voice profiles as J40. Cost: needs an 8 GB board with no other GPU jobs.
  • You already run Rockchip boards → reComputer RK3588, or RK3576 for a lower cost. Cost: 528 ms and 1020 ms to first audio.
  • Chinese and English only, lowest cost → Pi 5 (8GB) on CPU. Cost: no multilingual profile.

Before deploying: SSH access to the host, internet for the first start, and free disk for the profile you pick.

Deployment Options

Deploy Speech Service

Deploy streaming ASR + TTS service to your edge device via SSH

2 steps · ~15min

Edge Device
recomputer_j40
recomputer_rk3576
recomputer_rk3588

FAQ

Yes, after the first deployment. The first start downloads the image and models; after that recognition and synthesis run entirely on the host.

Didn't find your answer?
Contact Us
We Are Glad to Be Your Hardware Partner !
Next