OpenClaw AI Gateway

Deploy OpenClaw AI messaging gateway on reComputer, with optional local AI model for privacy-first conversations.

Beginner15minOn-Device LMSource Code

reComputer J4012, the host for the AI compute gateway route that runs the model locally

Reusable Site Templates

Places where staff or customers should ask an AI inside the chat apps they already use, without a separate integration per platform.

  • A shared team assistant — one AI assistant in a Slack, Discord, DingTalk or Feishu group for the whole team.
  • A personal assistant in WeChat or Telegram — chat with models such as DeepSeek or OpenAI right in the messaging app.
  • Conversations that must not reach an AI provider — run the model locally on a Jetson, so message content is not sent to a third-party AI.

Not a fit: work that needs large-model reasoning quality, since the local route runs 2B-4B models. The cloud route sends message content to the AI provider you configure.
How it works

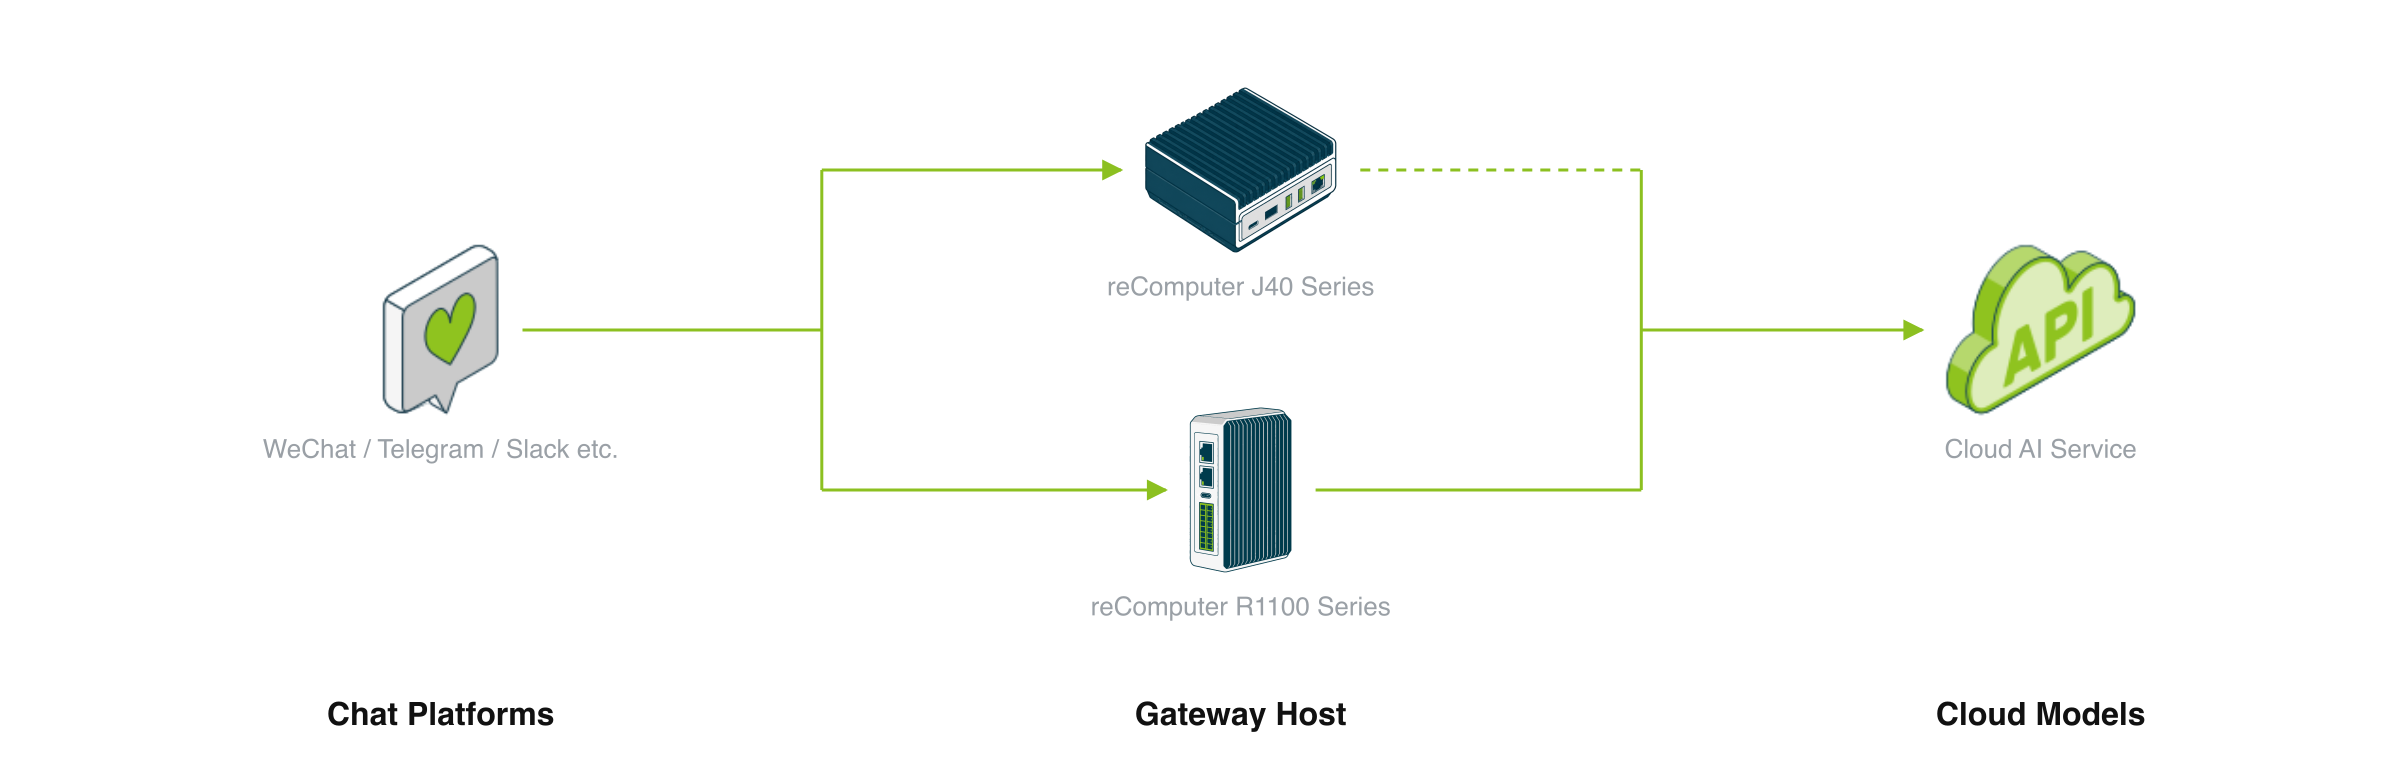
OpenClaw device composition: chat platform messages reach a reComputer J40 Series or reComputer R1100 Series gateway host; the R1100 connects to a cloud AI service, and the J40 optionally does too

Three pieces: the chat platforms you already use, a reComputer running the gateway, and the AI model that answers. The gateway passes each message to the model and sends the reply back to the same platform. The model can run on the same Jetson or be a cloud service.

Chat Platforms

WeChat, Telegram, Discord, Slack, DingTalk, Feishu and more than 20 platforms in all, added one by one in the gateway's web page.

  • Credentials once per platform: enter the bot token or webhook the page asks for, then authorize.
  • One integration to maintain: changing the model or adding a platform happens in the gateway, not on each platform.

How well it works

The table lists what each route provides, and its limits.

RouteWhat it doesLimit
AI compute gateway (reComputer J40 Series)A local model answers; message content is not sent to an AI provider; no token feesLocal models are 2B-4B, and 4B is slower than 2B
Lightweight gateway (reComputer R1100 Series)Connects cloud models such as OpenAI or DeepSeek, switchable any timeReply speed depends on the cloud service; pay per call; message content goes to the cloud

Both routes connect more than 20 chat platforms at once.

What you get out of it

Once deployed, these are the entry points.

EntryWhat it doesNotes
Each chat platformUsers send messages; AI replies land in the same platformAdded under Channels in the gateway page
HTTP 18789Gateway management page: test chat, platform connections, model settingsBound to localhost by default; remote access via SSH tunnel and Gateway Token
HTTP 11434Local model servicePresent only when the compute gateway enables a local model

The Gateway Token is kept in a config file under the deploying user's home, readable only by that user.

How to deploy

Tell us about your site — we work out the hardware, then you connect the data and follow the steps.

Message Data

Can message content be sent to a cloud AI provider? The gateway software is the same either way. This decides where the model that answers runs.

FAQ

For cloud models, a reComputer R1100 Series; the gateway needs only 4GB of disk and 4GB of RAM. For a local model, a reComputer J40 Series, which then needs 12GB of disk and 8GB of RAM. Both need Docker installed first.

Didn't find your answer?
Contact Us
We Are Glad to Be Your Hardware Partner !
Next