Conversational Voice AI
Scenario details
Interaction and deployment options for desktop voice robots, industrial voice control and smart home assistants.
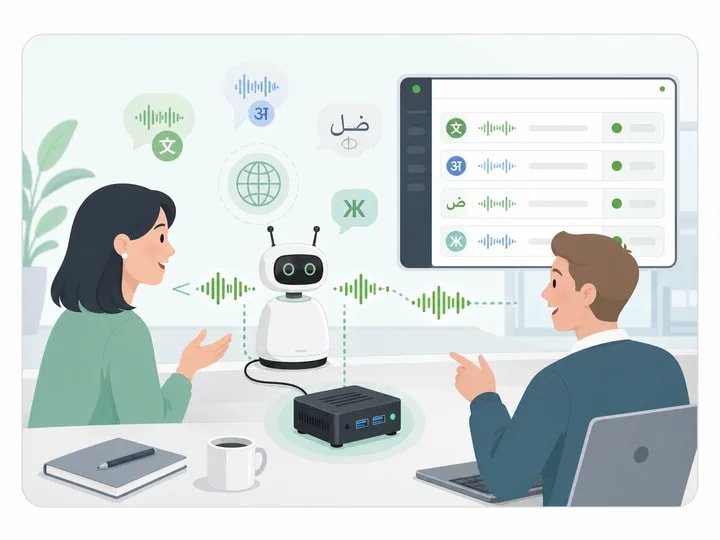
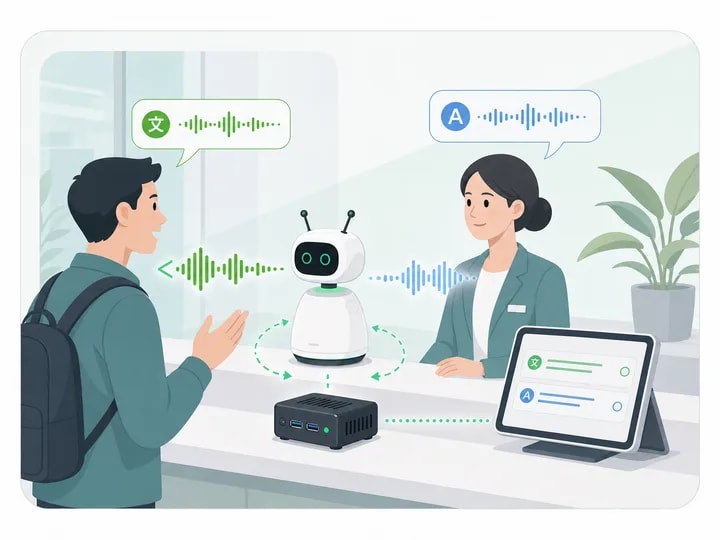
Understand and reply on the device
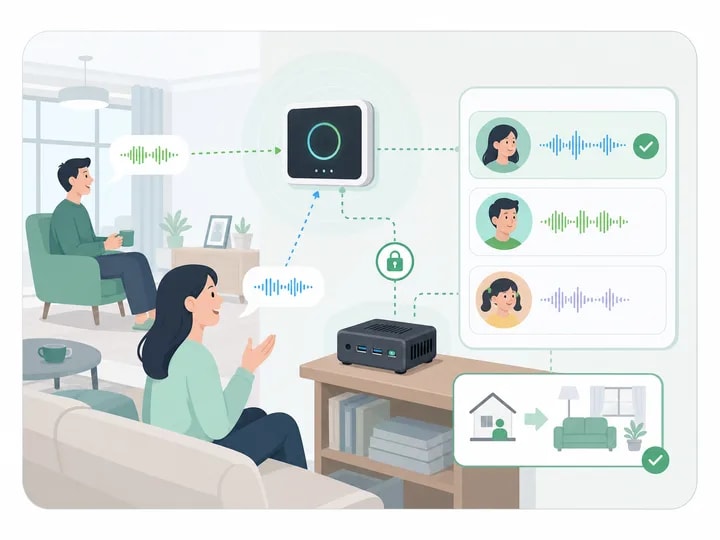
Recognizes multiple languages on the device and replies by voice; fits desktop devices, meeting terminals and guide kiosks for two-way voice conversation.
Core Advantages
- Multilingual Recognition
- Barge-in
- Tiered Voice Quality
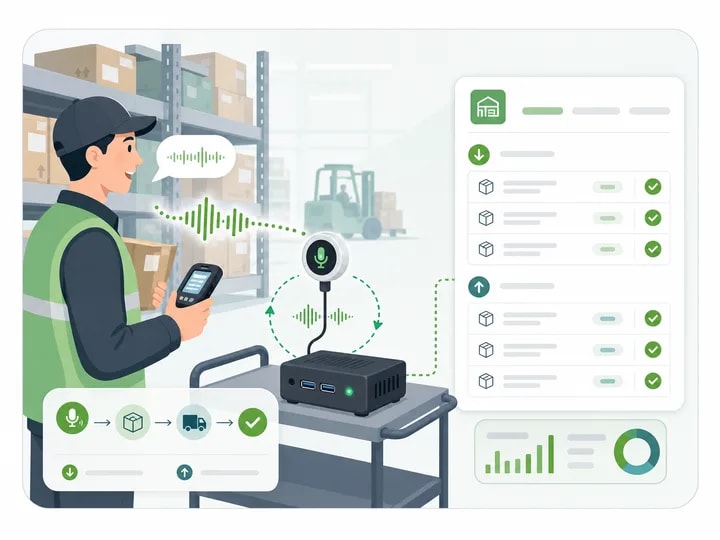
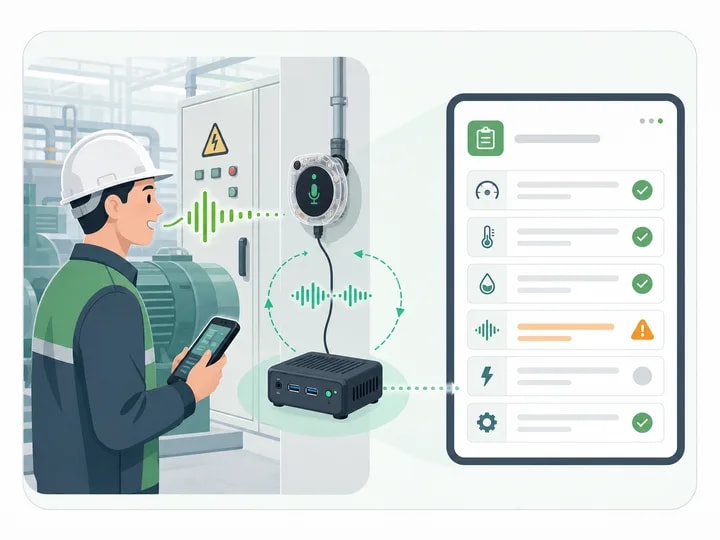
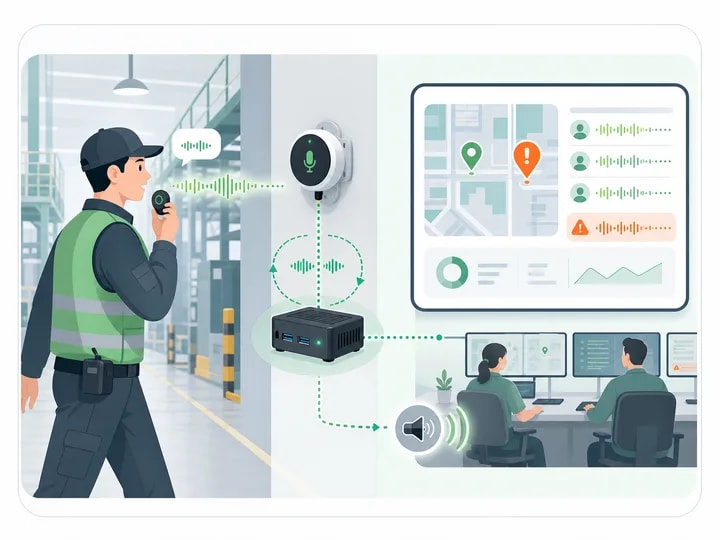
Voice device control & field data entry
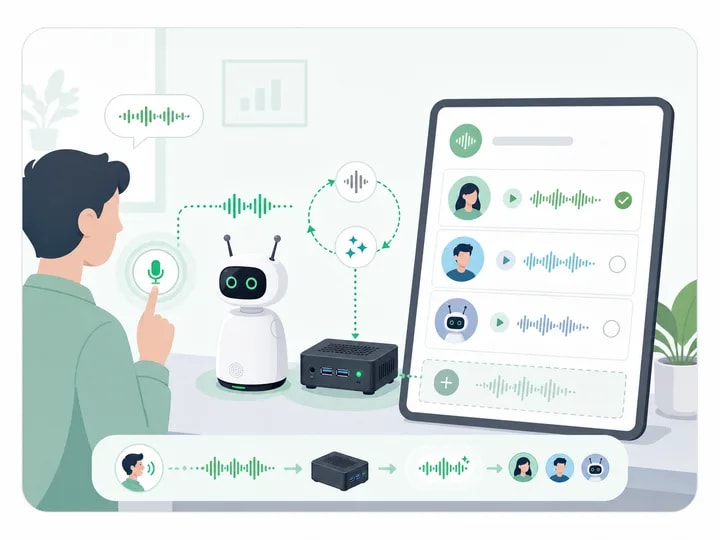
Voice replaces UIs & scanners in warehouses & workshops. Workers use natural language for logging, inspection, patrol forms & alerts. Local ASR outputs structured text for WMS, MES & IoT.
Core Advantages
- Lower Op Barrier
- Weak-Network Ready
- Structured Output
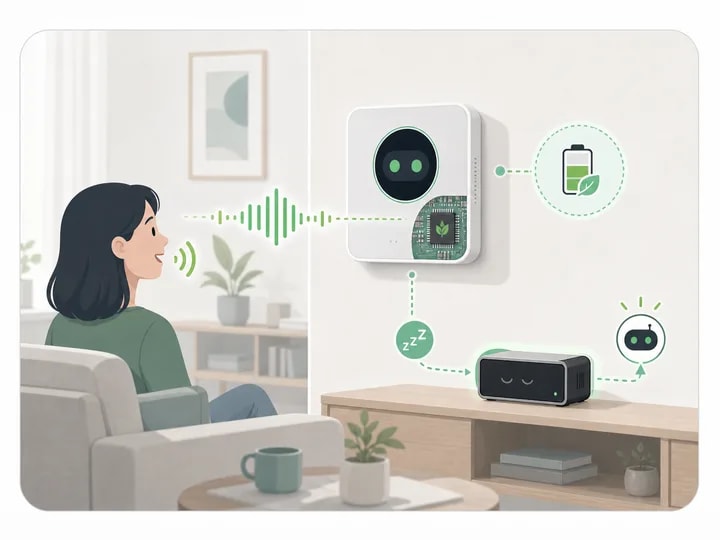
Wake, then handle it locally — even offline
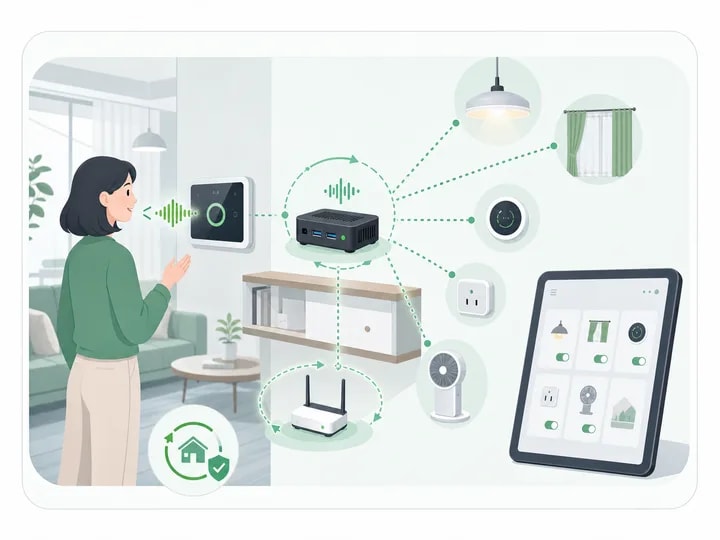
XIAO ESP32S3 is the low-power wake frontend; after wake-up the main unit handles recognition, conversation and the spoken reply, and controls devices through local protocols such as Matter, HomeAssistant and Mi Home. With the on-device LLM, commands are processed locally and work offline.
Core Advantages
- Low standby power
- Custom wake word
- Local Control
Deployment & Selection
The configurator works through use case, voice tier, concurrency, on-device LLM, microphone setup and latency target to reach specific models.
Not sure which to choose? See the full selection guide →
Use Case
Three Models: Frontend, Hybrid, All-in-One
Voice compute placement determines capability ceiling & per-unit BOM. Three common models:
Core Advantages
- Frontend only
- Hybrid
- All-in-One (Frontend + Large AI Box)
| Image | Hardware | Voice Concurrency (voice-only) | Voice Capabilities | Local LLM |
|---|---|---|---|---|
 | reRouter CM4 Series | 1 channel | Machine Voice | Cloud optional |
 | reComputer RK3576 Series | 1 channel | Simulated Voice | 4B–7B (w/ RK1828 card) |
 | reComputer RK3588 Series | 1 channel | Simulated Voice | 4B–7B (w/ RK1828 card) |
 | reComputer J30 Series | 1 channel | Natural Voice | ~2B |
 | reComputer J40 Series | 2–3 channels | Natural Voice | 4B–7B |
 | reComputer J50 Series | 3+ channels | Natural Voice | 7B–14B |
 | NVIDIA Jetson AGX Thor Developer Kit | 6+ concurrent (voice-only) | Realistic voice | 14B–32B |
Choose AI Compute Box by Capability
Compute boxes are tiered by voice capabilities. The table below is the device list for this scenario (by family): voice-only concurrency, voice capability, and deployable local-LLM size per family. Pick exact models, configurations, and accessories in the configurator below (see next tab for mic & speaker selection). Note: running a local LLM on the same device as the voice pipeline reduces performance and increases latency; for high concurrency plus large models, choose a higher compute tier.
Core Advantages
- Wake & Commands
- Standalone
- Pro-tier natural voice
- High concurrency + advanced LLM
| Product | Type | Chip | Pickup Range | Coverage Angle | Built-in Amp | Core Algorithms |
|---|---|---|---|---|---|---|
 reSpeaker Lite | Linear 2-Mic | XMOS XU316 | 3m | 180° | 5W | AEC · DoA |
 reSpeaker XVF3800 | Circular 4-Mic | XMOS XVF3800 | 5m | 360° | 5W | AEC · DoA · Multi-beamforming |
 reSpeaker Clip | Wearable 2-Mic | nRF5340+nRF7002 | 3m | 360° | — | Noise reduction (SpeexDSP) |
 reSpeaker Flex Circular-4 | Circular 4-Mic | XMOS XVF3800 | 5m | 360° | 10W | AEC · DoA · Multi-beamforming |
 reSpeaker Flex Linear-4 | Linear 4-Mic | XMOS XVF3800 | 5m | 180° | 10W | AEC · DoA · Multi-beamforming |
Three Core Advantages of the reSpeaker Series
Core Advantages
- Hardware pickup
- On-board acoustics
- Open SDK
FAQ
It depends on where the conversation model runs. With the on-device LLM (RK3588 with an RK1828 card, or J4012), recognition, conversation and speech synthesis all run on the device, and it works offline after images and models are downloaded on the first online start. With a cloud model, conversation needs the network; recognition and speech synthesis still run on the device.
It depends on the compute tier: the RK series and J3011 run a single channel; J4012 supports 2–3 channels; J5012 reaches 3+ — all figures are for the pure voice pipeline (recognition + synthesis) only. Once a local LLM is added, the model consumes the compute, so plan for a single channel. Multi-site deployments can also scale out with more devices.
Audio does not. Recognition and speech synthesis run on the device and recordings are not uploaded. With a cloud model, the recognized text is sent to the model endpoint you configure; with the on-device LLM, the text stays on the device too. Business-system integrations receive the recognized text.
Yes. The wake word can be any short Chinese or English phrase, applied at startup, with strict, balanced and sensitive settings. Voices come in machine, simulated and natural tiers; the natural-voice model on J4012 can clone a voice from reference audio.
1-year hardware warranty plus 1 year of technical support. Custom development work (own apps, deep customization) goes through the customization channel, scoped by the project team.
Yes. The Seeed devices used in this solution can be customized with your own logo, enclosure, packaging and pre-loaded firmware, and existing models can be adapted to add or drop interfaces and features. See Customization Service for scope and process, or .